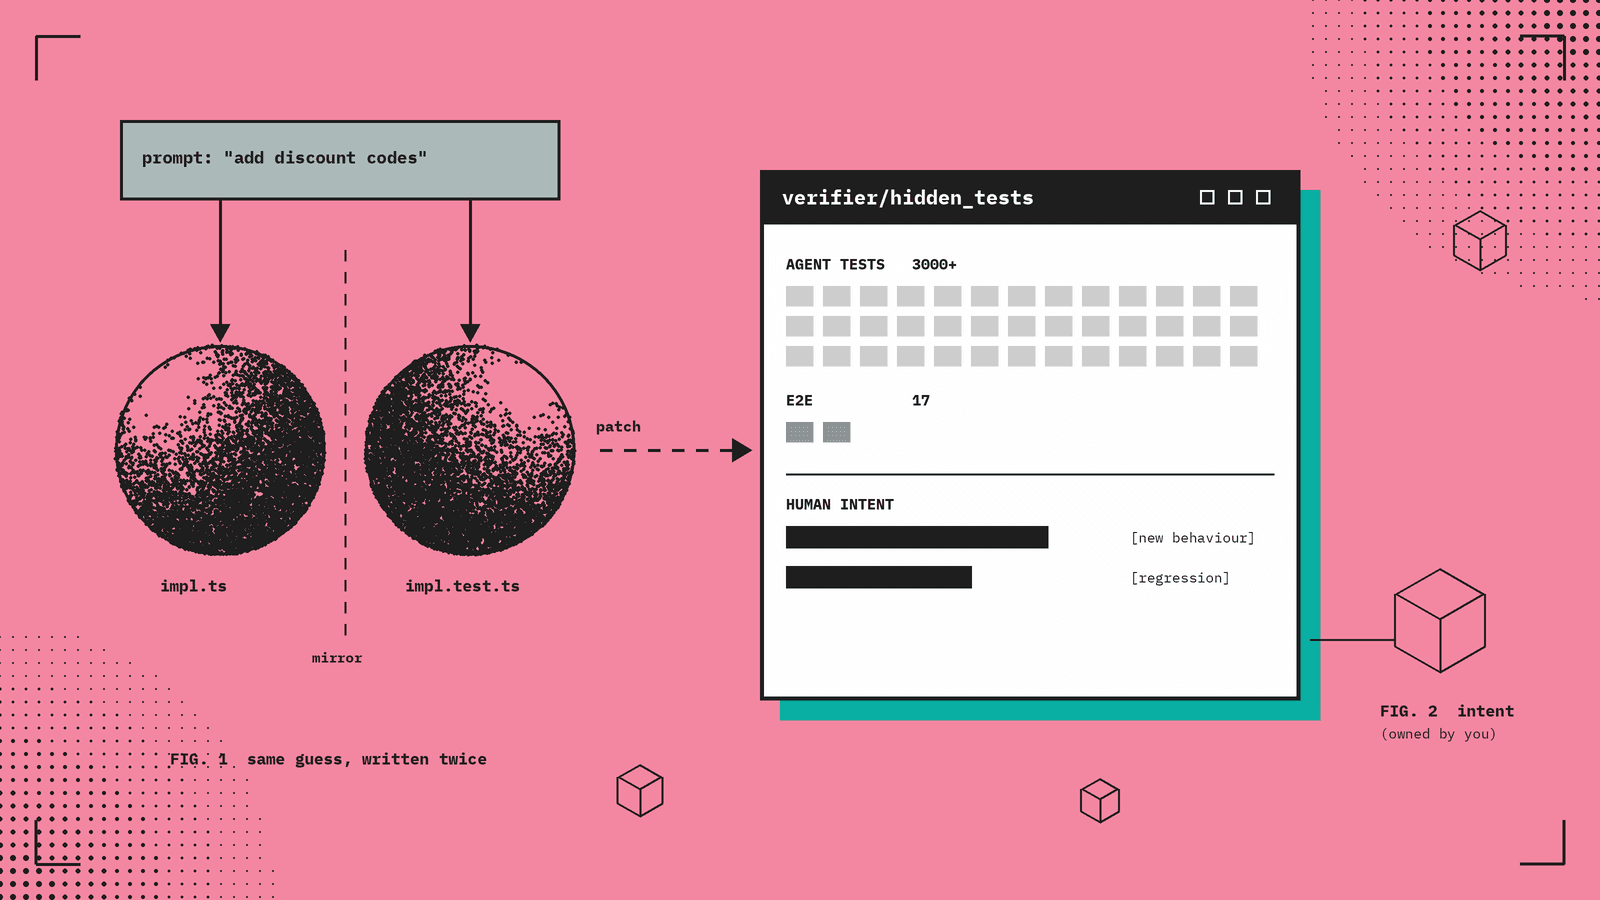
Your agent's tests are marking its own homework
Kun Chen banned Sonnet 5.5 from writing its own tests on DeepSWE and nothing got worse. Tests aren't dead, but a test written from the agent's own guess is no check at all.
Stories, insights, and experiments from my corner of the internet.
Kun Chen banned Sonnet 5.5 from writing its own tests on DeepSWE and nothing got worse. Tests aren't dead, but a test written from the agent's own guess is no check at all.
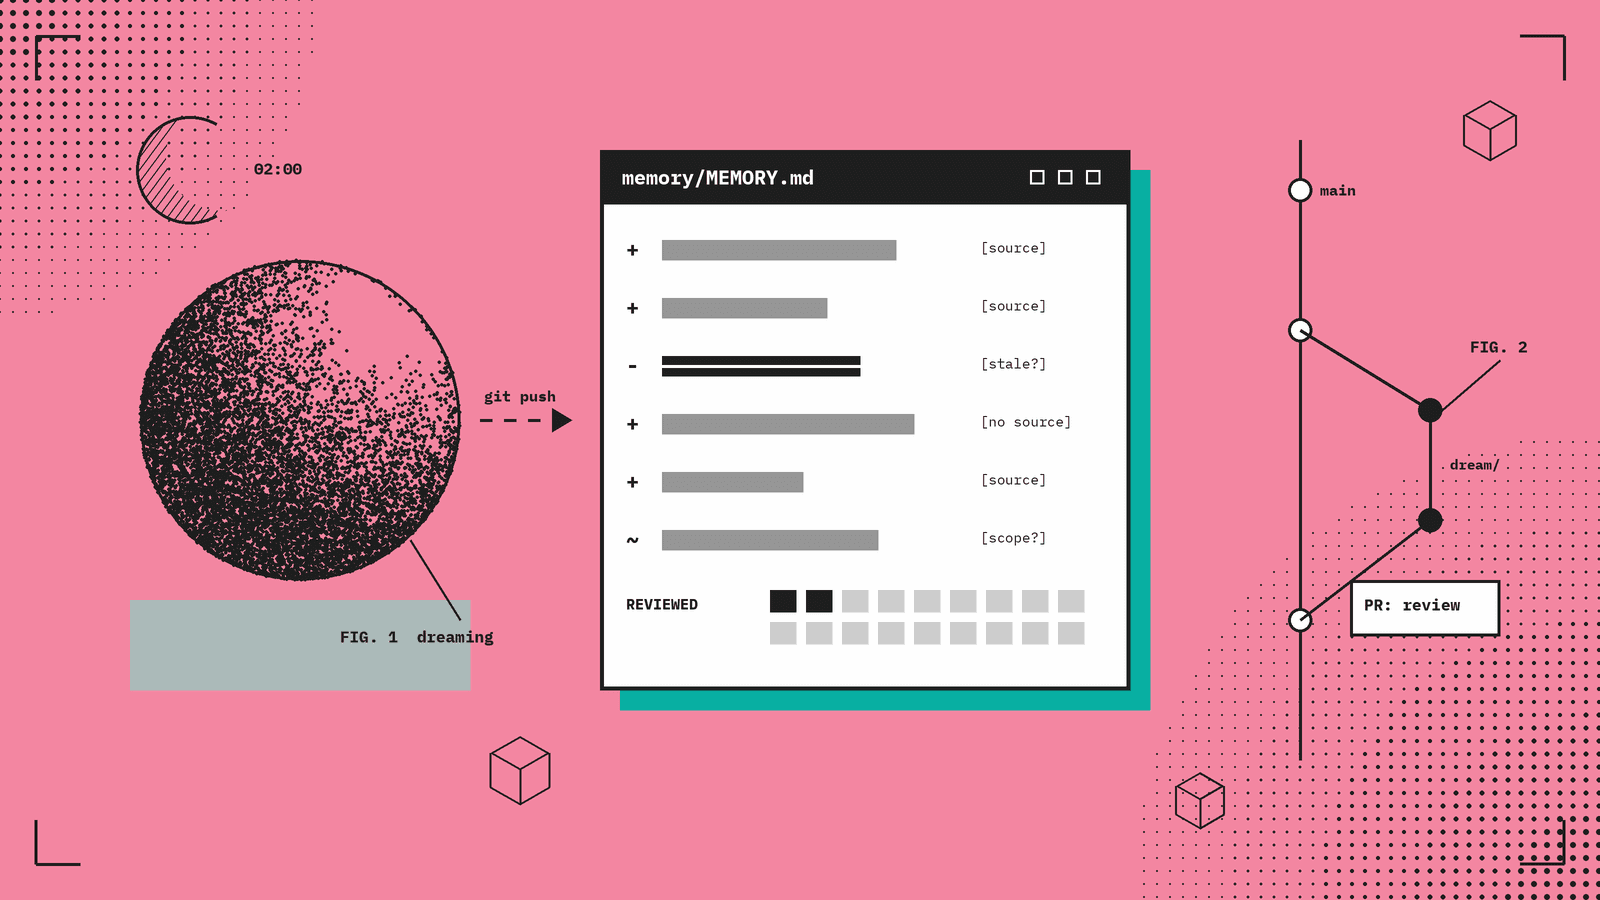
Cognition put Devin's memory in a git repo of markdown and lets a nightly agent tidy it. Lovely primitive, but the writes are where memory goes wrong, so review them like code.
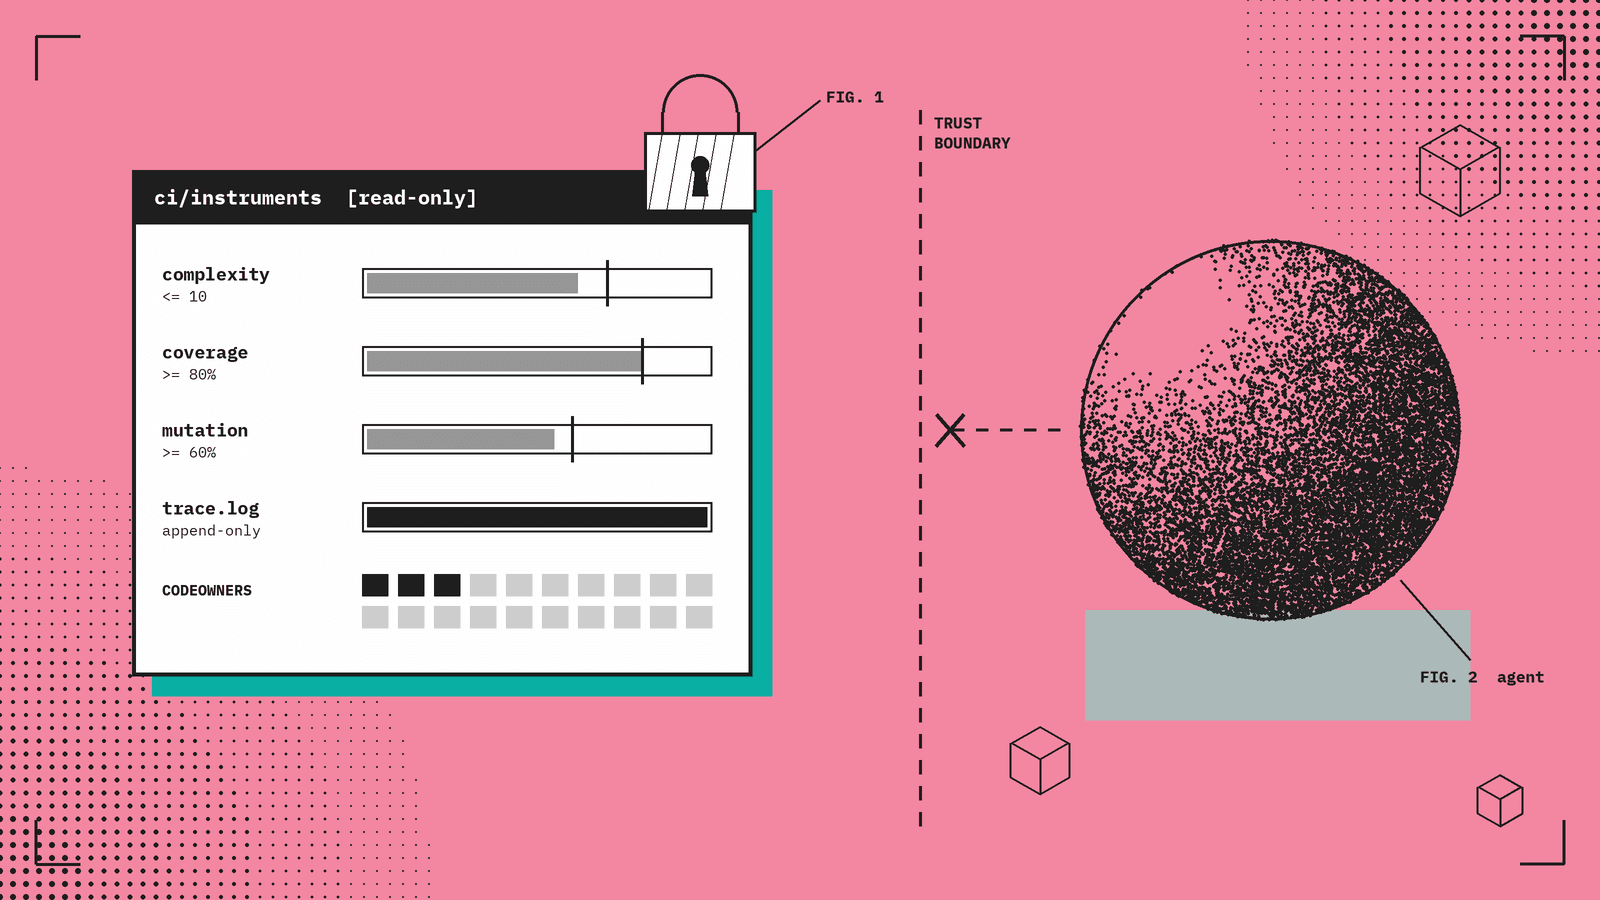
Uncle Bob doesn't read agent code anymore, he measures it. Fair enough, but the agents can edit the measurements, so decide who owns the instruments before you stop looking.
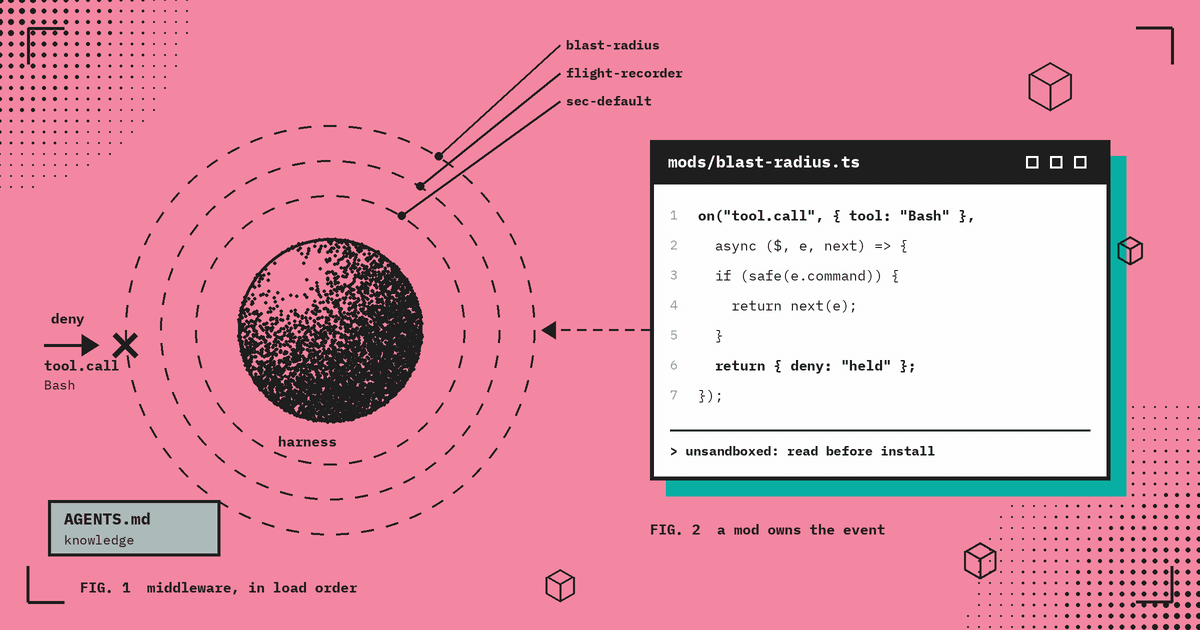
Skills and AGENTS.md still steer with knowledge. Mods are in-process TypeScript that can deny a tool call and draw UI, so the edge moves to the harness your team ships.
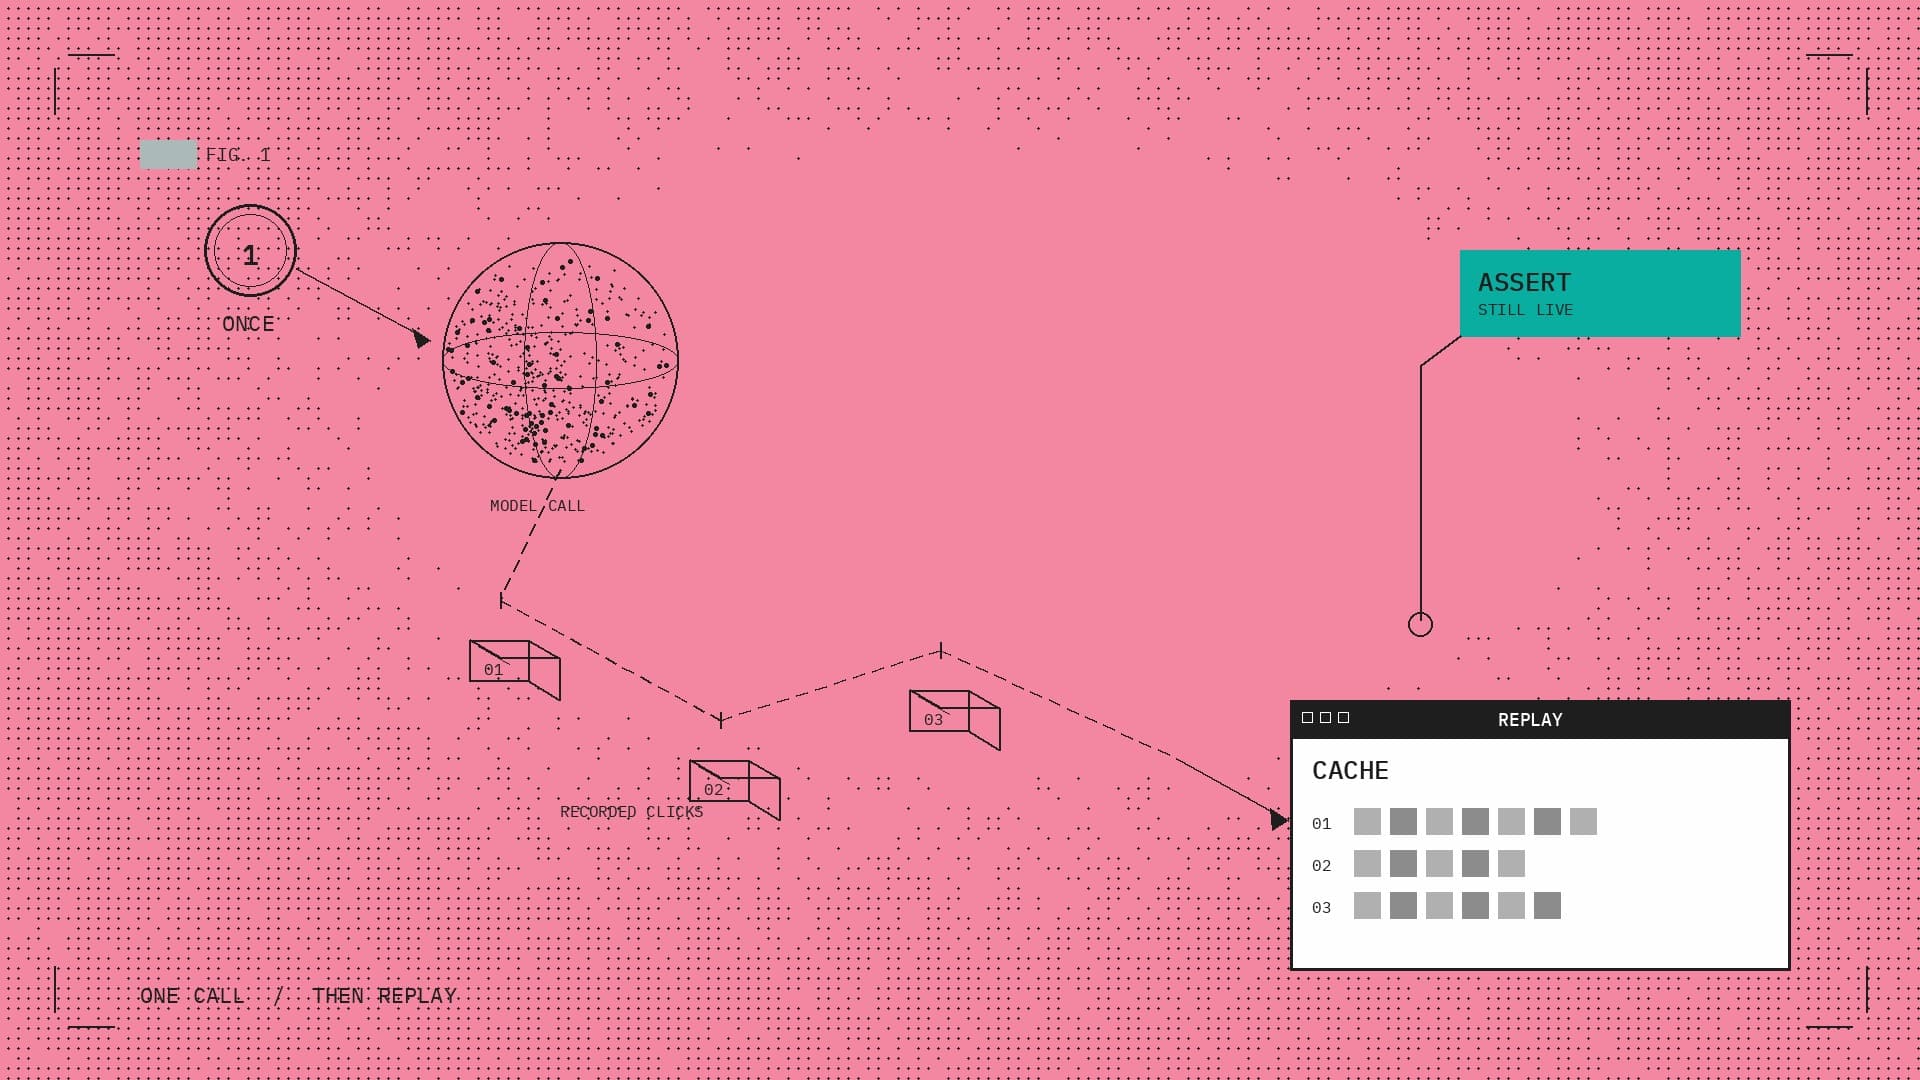
Tester Army’s open source TypeScript e2e runner mixes locators with agent goals, then caches a verified agent step so the next run replays it without calling the model.
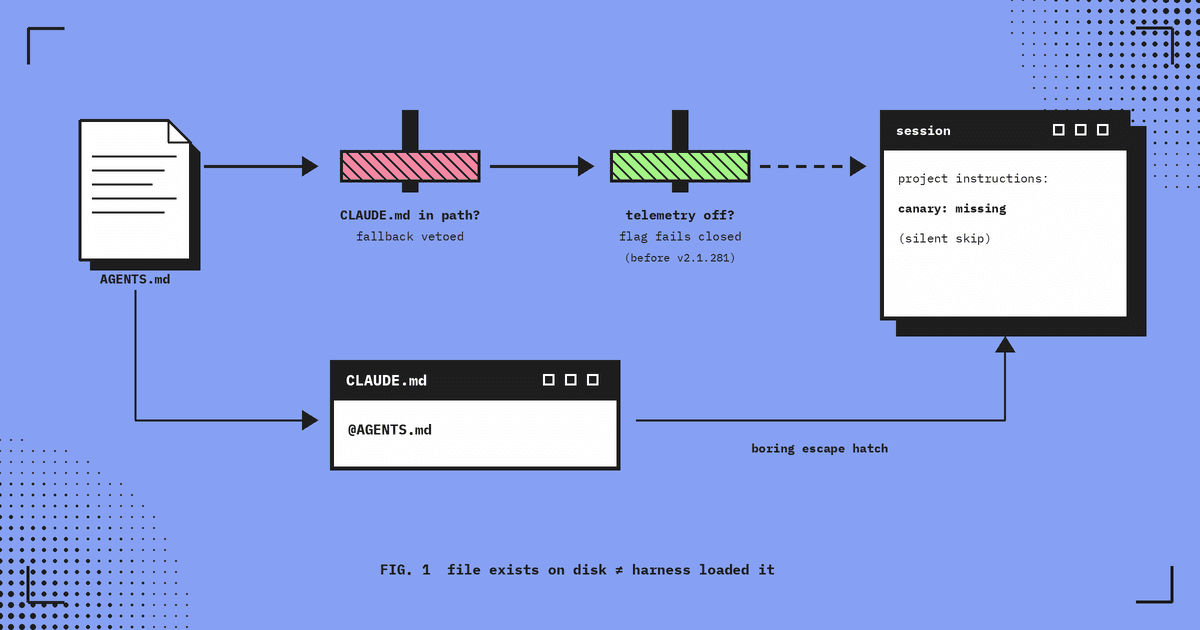
Claude Code can fall back to AGENTS.md, but CLAUDE.md still wins, and for a window a fail-closed flag could skip the file silently. Verify the harness ingested it.
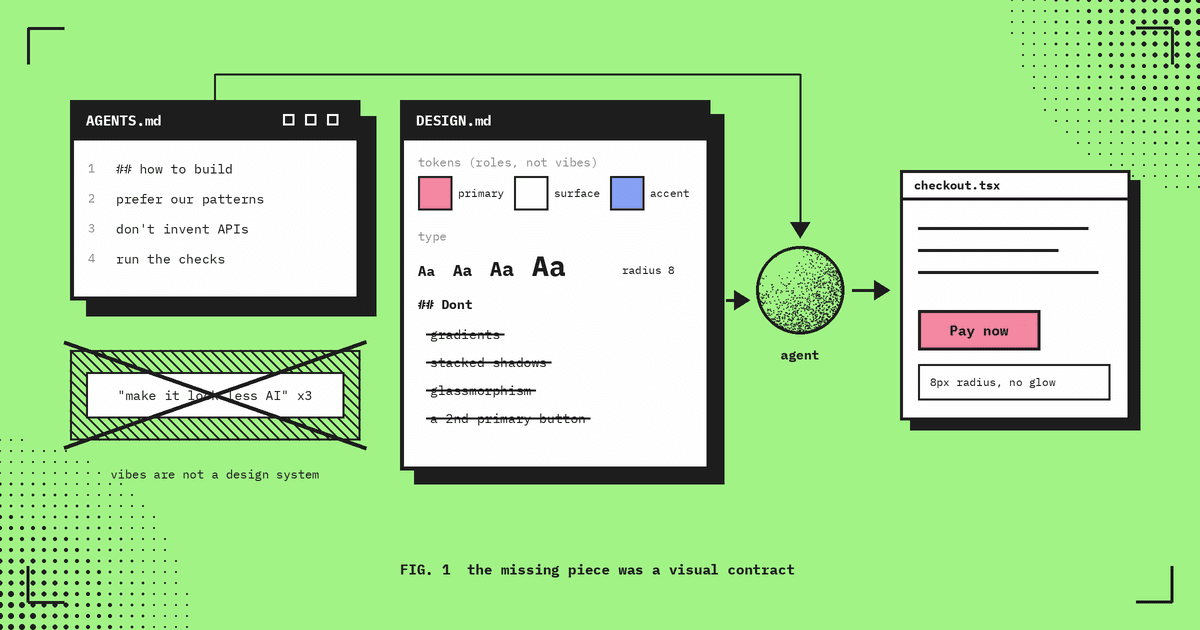
Coding agents ship clean TypeScript and ugly UI because we gave them build intent without a visual contract. Put a DESIGN.md (with a Dont list) next to AGENTS.md.
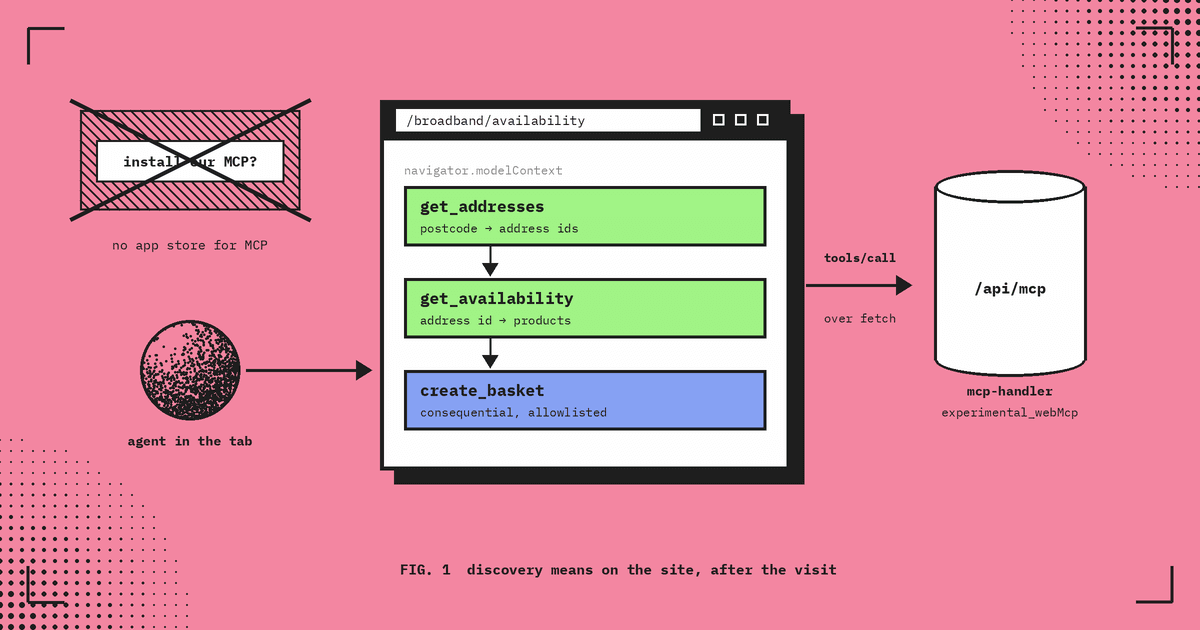
Most people will never install your MCP into Claude or ChatGPT. Nobody downloads an app for a one-off sale, and MCP does not even have an app store. WebMCP is for agents already on the page.
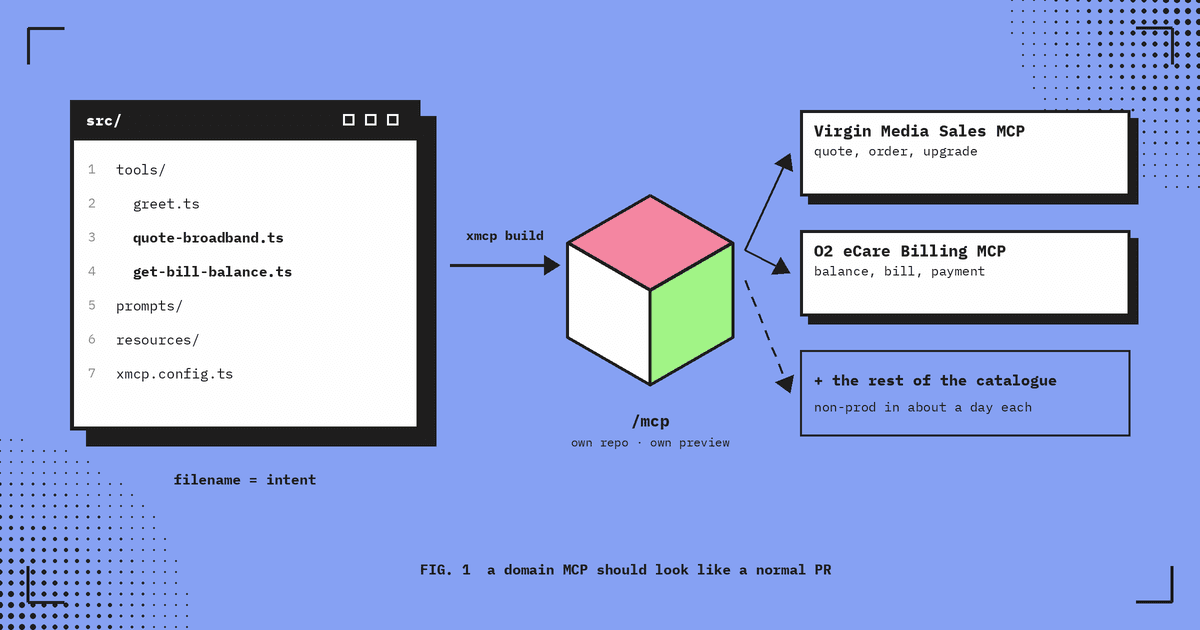
For a Next.js / TypeScript dev house that needs domain MCPs fast, an xmcp's file-based routing plus Vercel deploy is the practical answer. Not download-chart wins. DX fit.